

Overview

The MarineEval dataset is designed to evaluate the capabilities of general vision-language models (VLMs) in addressing domain-specific marine tasks through visual question answering. It comprises 2,000 questions spanning 7 dimensions and 20 sub-dimensions, encompassing a broad spectrum of marine knowledge and skills, including species identification, conservation, and other related areas.
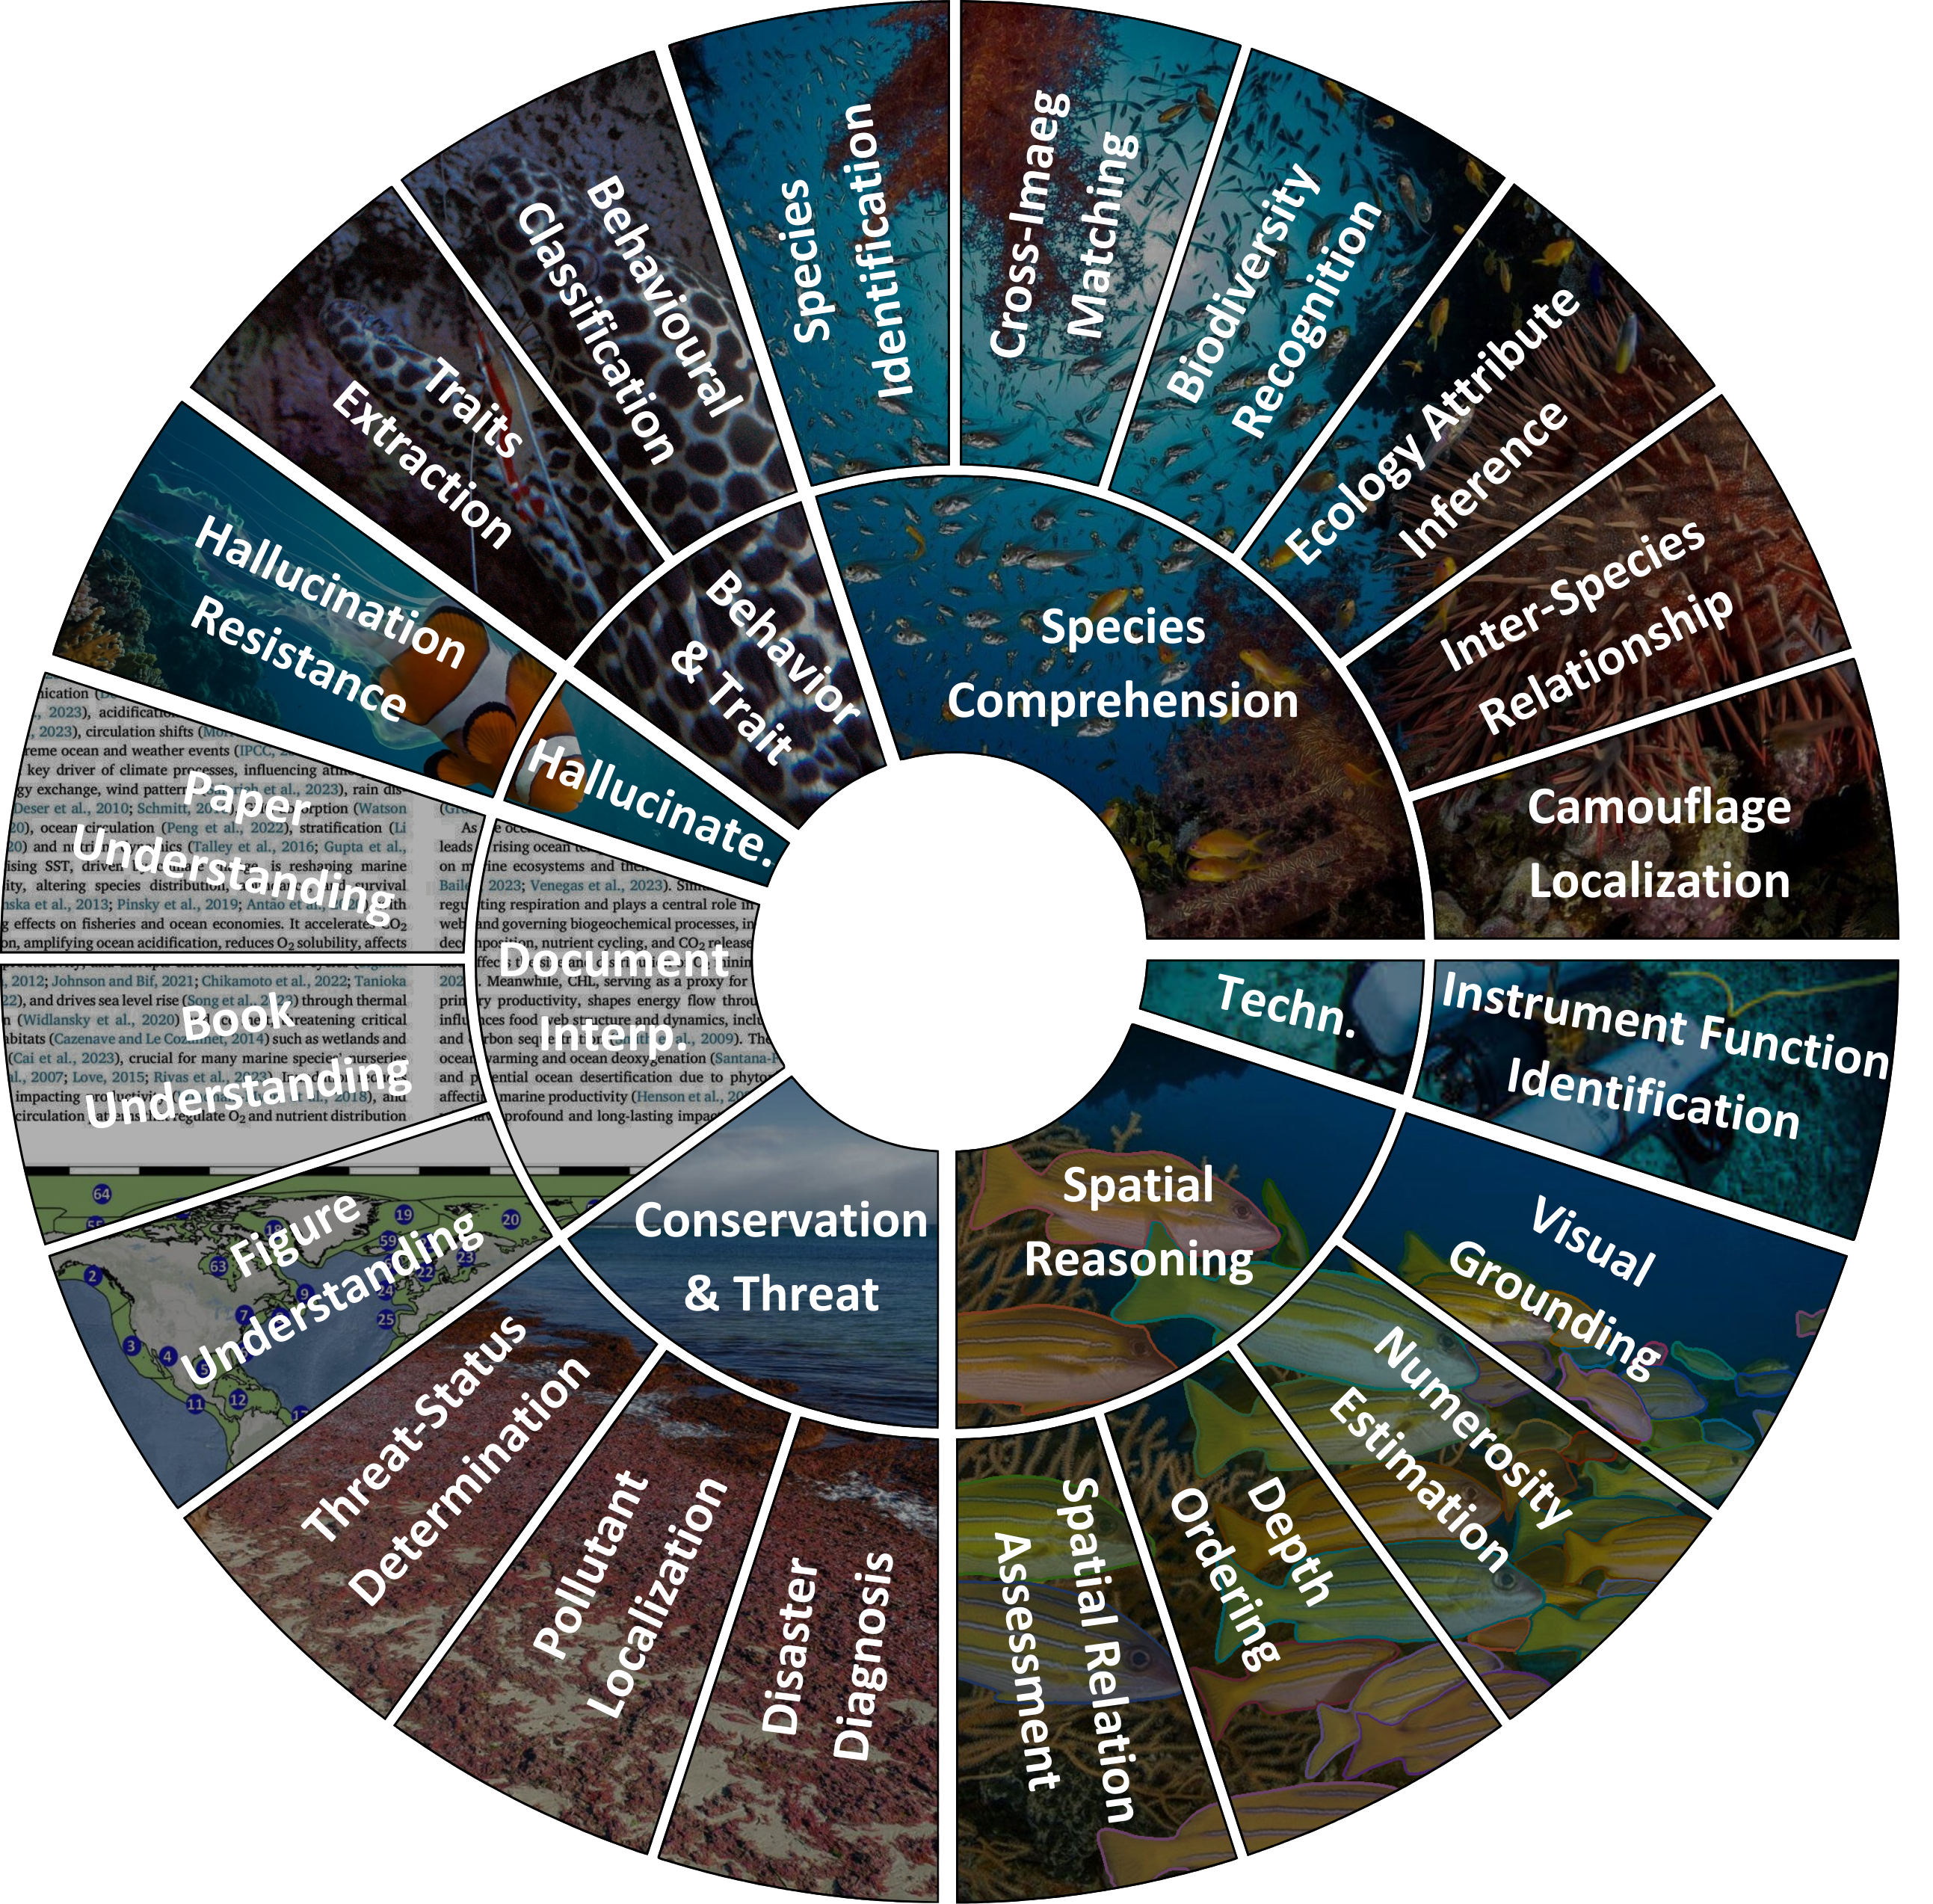
Figure 2. Dimension overview.
Dataset Overview
Statistic
| #. of Questions | #. of Dimensions | #. of Sub-Dimensions |
|---|---|---|
| 2,000 | 7 | 20 |
Figure 3. Distribution of question types in the
MarineEval dataset.
Benchmark
Figure 4. Average accuracy across 7 task dimensions for
different model categories.
| Model | # Params. | B&TE | C&TA | DI | HR | MTU | SR | SC | Avg. | Total |
|---|---|---|---|---|---|---|---|---|---|---|
| Open-source VLMs | ||||||||||
| DeepSeek-VL-chat | 1.3B | 27.86 | 39.33 | 11.00 | 59.00 | 34.31 | 22.25 | 18.33 | 30.30 | 24.96 |
| OpenFlamingo | 2B | 20.90 | 40.33 | 5.33 | 60.00 | 21.57 | 8.25 | 9.83 | 23.74 | 17.62 |
| Mini-Monkey | 2B | 44.28 | 50.33 | 33.00 | 58.00 | 74.51 | 12.75 | 27.67 | 42.93 | 34.45 |
| InternVL-2.5 | 4B | 65.17 | 56.67 | 54.00 | 64.00 | 80.39 | 16.75 | 29.33 | 52.33 | 42.54 |
| LLaVA-1.6 Vicuna | 7B | 68.66 | 52.00 | 38.67 | 53.00 | 71.57 | 34.00 | 37.33 | 50.75 | 44.73 |
| InternLM-XComposer2.5 | 7B | 64.18 | 60.33 | 49.33 | 52.00 | 75.49 | 14.00 | 30.17 | 49.36 | 41.14 |
| LLaVA-Next | 8B | 44.78 | 69.67 | 25.67 | 32.00 | 54.90 | 32.00 | 26.67 | 40.81 | 37.54 |
| InternVL-2 | 8B | 55.22 | 55.00 | 46.00 | 65.00 | 78.43 | 16.50 | 34.17 | 50.05 | 41.44 |
| InternVL-2.5 (26B) | 26B | 35.32 | 41.67 | 47.00 | 66.00 | 74.51 | 25.00 | 32.33 | 45.98 | 38.59 |
| LLaVA-Next-Qwen | 32B | 67.16 | 60.00 | 38.33 | 65.00 | 72.55 | 16.50 | 43.67 | 51.89 | 44.78 |
| LLaVA-1.6 Hermes-Yi | 34B | 68.66 | 52.00 | 38.67 | 53.00 | 71.57 | 34.00 | 37.33 | 50.75 | 44.73 |
| InternVL-3 | 38B | 74.13 | 48.33 | 60.33 | 68.00 | 78.43 | 22.50 | 39.83 | 55.94 | 47.53 |
| Avg. across models | – | 53.81 | 52.77 | 37.19 | 59.42 | 71.19 | 21.23 | 30.27 | 46.14 | 39.17 |
| Close-source VLMs | ||||||||||
| Claude-3.7-Sonnet-Vision | – | 68.16 | 53.67 | 52.33 | 71.00 | 83.33 | 24.50 | 45.17 | 56.88 | 48.93 |
| Gemini-2.0-Flash-Vision | – | 65.17 | 60.67 | 59.67 | 74.00 | 87.25 | 29.00 | 55.33 | 61.59 | 55.07 |
| Grok-2-Vision | – | 77.61 | 54.67 | 27.33 | 74.00 | 70.59 | 34.50 | 54.00 | 56.10 | 50.42 |
| GPT-4o-Vision | – | 69.15 | 44.67 | 51.67 | 72.00 | 62.75 | 26.50 | 40.50 | 52.46 | 45.58 |
| Qwen-VL-Plus | – | 52.24 | 41.00 | 42.00 | 71.00 | 85.29 | 25.00 | 39.50 | 50.86 | 42.39 |
| Avg. across models | – | 66.07 | 50.34 | 46.20 | 72.40 | 77.64 | 27.90 | 46.10 | 55.18 | 48.08 |
| Human Performance | ||||||||||
| General Background | – | 68.65 | 54.33 | 60.17 | 82.00 | 76.96 | 51.50 | 31.42 | 60.72 | 51.75 |
| Marine Background | – | 75.00 | 70.33 | 69.67 | 83.00 | 72.00 | 64.00 | 57.50 | 70.31 | 66.35 |
Table 1. The average accuracy across 7 task
dimensions. Abbreviations: Behavior & Trait
Extraction (B&TE), Conservation
& Threat Analysis (C&TA),
Document Interpretation (DI),
Hallucination Resistance (HR), Marine
Technology Understanding (MTU), Spatial
Reasoning (SR), Species Comprehension
(SC). “–” indicates the number cannot
be computed.
Citation
@InProceedings{Wong_2026_WACV,
    author    = {Wong, Yuk-Kwan and Liang, Haixin and Ma, Zeyu and Chen, Yiwei and Zheng, Ziqiang and Gotama, Rinaldi and Sebastian, Pascal and Sparks, Lauren D. and Yeung, Sai-Kit},
    title     = {ORCA: Object Recognition and Comprehension for Archiving Marine Species},
    booktitle = {Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision (WACV)},
    month     = {March},
    year      = {2026},
    pages     = {1597-1609}
}